AI Agents
Building My Own AI Agent Environment: Lessons Learned from OpenClaw and Hermes
A real-world journey building a personal AI agent environment with OpenClaw, Hermes, and local AI models. Learn what worked, what failed, and what I discovered.
Writing about local AI, open models, practical deployment, and the tools that make them useful.
AI Agents
A real-world journey building a personal AI agent environment with OpenClaw, Hermes, and local AI models. Learn what worked, what failed, and what I discovered.
Local AI
The new Ornith-1.5 open-weight family (35B-A3B MoE, 9B, MIT) fits inside one consumer GPU. What you should actually run on a 24 GB card, why its hybrid attention makes long context unusually cheap from the math, and when it replaces what you already host.
24GB Lab
A practical comparison of RunPod and Vast.ai for local AI users who occasionally need more VRAM than a 24 GB GPU can provide — with the stay-local vs rent vs buy decision worked out in order.
AI Agents
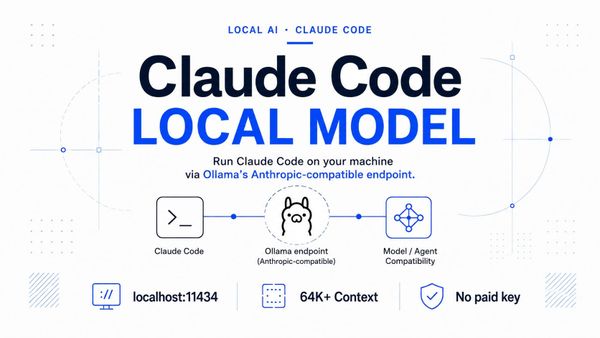
Claude Code can run against a model on your own machine, no paid key involved. Current Ollama does it with ollama launch claude — what the endpoint actually covers, which models to try first, and why the context window is the setting that matters.
Local AI
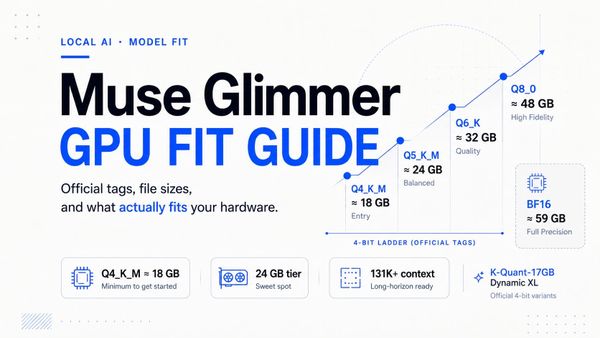
Meta Superintelligence Labs' new open model for local deployment lands with a real footprint. We map Muse Glimmer 30B's official quantization ladder against your card tier and Ollama tags, using exact file sizes.
Frontier AI
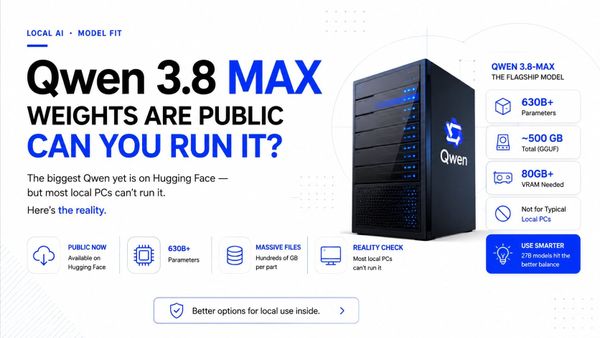
Qwen3.8-Max-class weights are now downloadable from Qwen on Hugging Face. Here's how large the A95B checkpoint really is, what the smallest GGUF costs, and why it is far beyond a typical local PC.
Local AI
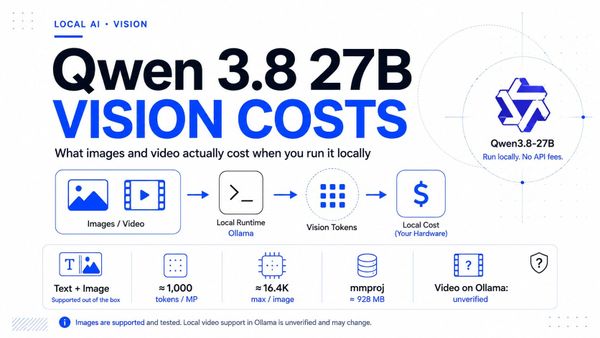
Images work out of the box in Ollama. Verified against the model's shipped configs: what each image costs in tokens, what the projector adds on GGUFs, and exactly where my verification stops at video.
24GB Lab
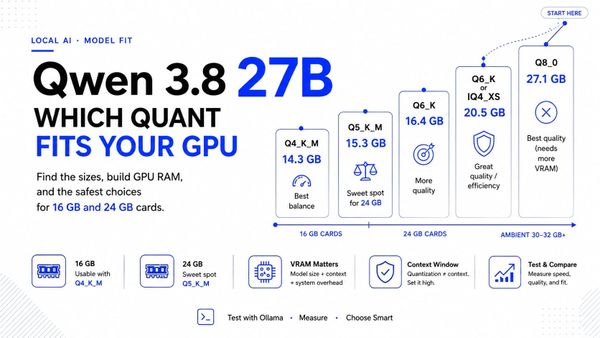
Exact Hugging Face file sizes for every Qwen3.8-27B GGUF, a blunt per-card recommendation (UD-Q4_K_M at ~24GB), when NVFP4 changes the maths on Blackwell, and two-minute checklist built from hard numbers.
24GB Lab
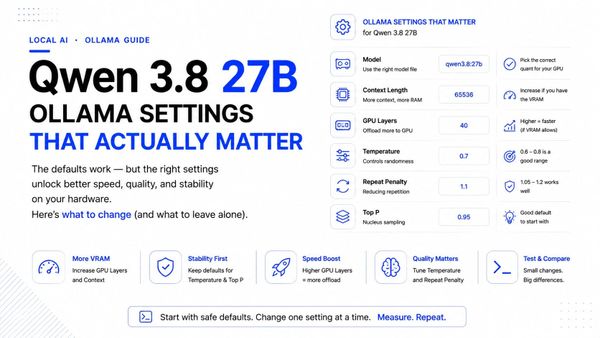
Why different context surfaces can show 262K and 131K at the same time, which Ollama defaults qwen38-27b hands you after a pull, what thinking-on-by-default costs in real use, plus a day-one checklist from one measured RTX 5090 Laptop GPU session.
24GB Lab
What Qwen 3.8 27B at 4-bit actually costs in VRAM and time on an RTX 5090 Laptop GPU, based only on retained client-side measurements.
Local AI
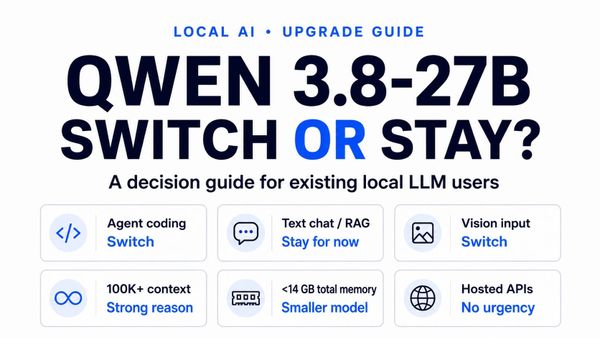
A decision guide for people already running a local LLM: what the vendor-published model card says about Qwen3.8-27B versus Qwen3.6-27B, where the reported differences actually matter agentically and multimodally, and how to fit it on your hardware.