Local AI
Qwen3.8-27B Q4 vs Q5 on 24GB VRAM: What 32K, 64K, and 128K Context Actually Cost
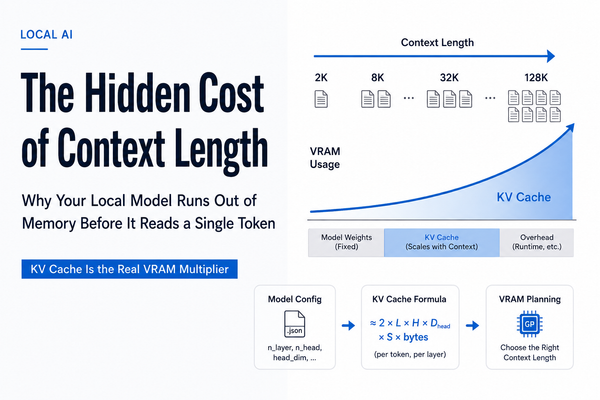
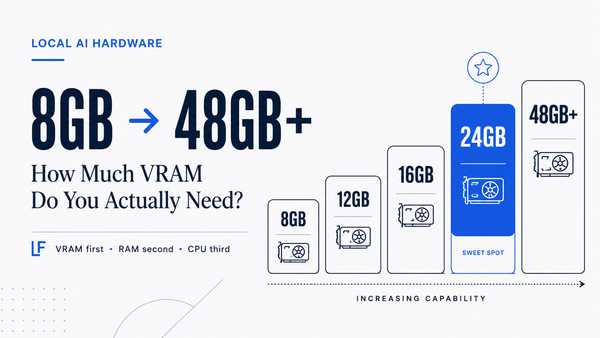
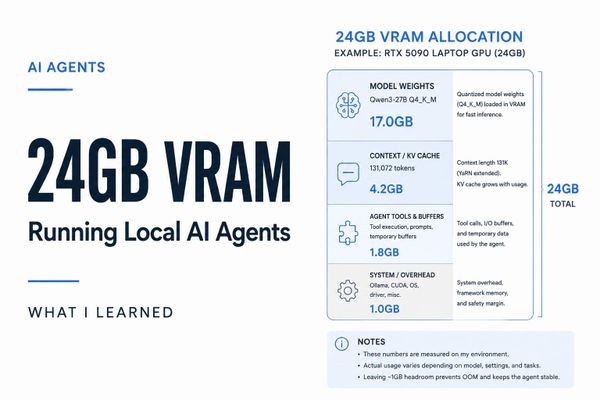
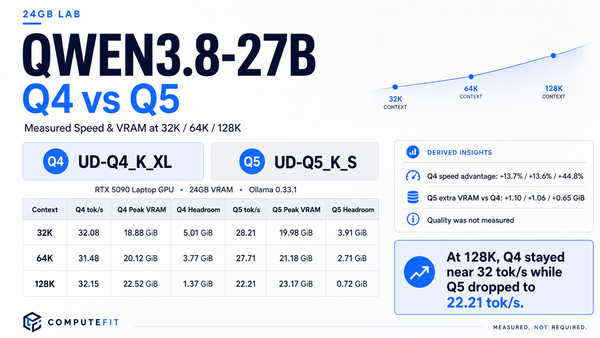
In ComputeFit's measured 24GB test, UD-Q4_K_XL ran Qwen3.8-27B at ~31-32 tok/s across 32K, 64K, and 128K context with more observed VRAM headroom than UD-Q5_K_S, whose speed gap widened to ~45% (derived) at 128K. Quality was not measured.